What is autonomous endpoint management?
Autonomous endpoint management (AEM) is an approach to managing laptops, desktops, servers, and other devices in which the platform detects problems, decides what to do within limits set by policy, and fixes them without waiting for a person. It covers patching, configuration, application health, and recovery, and it keeps people in charge of the rules rather than every individual task.
Put simply, traditional endpoint management tells IT what is wrong and then waits. Autonomous endpoint management closes that gap. The platform watches the state of every device continuously, compares it with the standard the organization has defined, and corrects deviations before a ticket is opened. A missing patch gets deployed. A security agent that has stopped running gets repaired. A device that has drifted from its approved configuration gets returned to it. People still write the standard, set the boundaries on what the system may change, and review what it did.
What separates AEM from ordinary automation is judgment and verification. Automation, sometimes called automated endpoint management or endpoint automation, runs a fixed sequence when a trigger fires, such as a patch job that starts at 2 a.m. every second Tuesday, and reports that the job completed.
AEM draws on data about risk, device state, and past outcomes to decide whether to act and which devices come first. It rolls a change out in widening rings, pauses or rolls back if failures climb, and then confirms that each device is actually in the desired state. Because it works inside endpoint management, AEM is an evolution of it, not a separate category.
Is autonomous endpoint management the same as unified endpoint management?
No. Autonomous endpoint management is a capability layer that builds on unified endpoint management (UEM), not a replacement for it. UEM provides the breadth and the control point: one console and one policy model across many device types. AEM adds the ability for the platform to decide, act, and verify on its own.
The gap AEM fills lies between a finding and a fix. In a UEM-only workflow, the console shows a failed patch, a missing application, or a drifted setting, and a person decides what to do, runs the action, and checks whether it worked. AEM takes over that sequence. It ranks problems by risk, acts, and confirms on the device that the intended state was reached, then retries, rolls back, or escalates if it was not. Because the loop runs continuously, a large share of routine work is finished before anyone opens a ticket.
Autonomy also depends on reach. Most endpoint management relies on a software agent inside the operating system, so a reimage, a replaced drive, or an accidental removal can cut the platform off from a device at the moment it needs attention. Anchoring the connection in device firmware avoids this. With firmware-embedded persistence, a component built into the device by the manufacturer monitors the management agent and reinstalls it if it goes missing, so the device stays reachable even after the operating system has been rebuilt.
Why autonomous endpoint management matters
Five pressures push organizations toward autonomous endpoint management.
Fleets are larger and often off the corporate network
Hybrid work means many devices spend most of their time on home broadband, shared workspaces, or cellular connections. Tools that depend on a device being on the corporate network or VPN at the right moment will miss some of the fleet some of the time. Mixed operating systems and ownership models also multiply the ways a routine task can fail.
Security controls fail quietly
Agents crash, conflict with other software, get removed during troubleshooting, or are wiped by a reimage. From the console, a failed control looks much like one that was never deployed. Health monitoring reveals the gap, and autonomous remediation closes it before the next audit or incident.
The window between disclosure and exploitation is short
When a serious vulnerability is disclosed, attackers read the same advisory as defenders. Approval queues, maintenance windows, and manual follow-up on failures leave devices exposed longer than they should be. Autonomy shortens the time from detection to verified fix.
IT and security teams are asked to cover more with the same people
Device counts, applications, and obligations grow faster than headcount. Chasing failed patches, re-enrolling devices, and reinstalling agents takes skilled people away from projects. Autonomous IT operations hands that routine work to the platform so people can focus on exceptions and risk.
Compliance expects continuous proof
Auditors increasingly want evidence that controls work on an ongoing basis, not only at audit time. Evidence collected by hand is slow and stale the moment it is collected. A platform that enforces the standard continuously and logs each action produces evidence as a by-product.
Core capabilities of autonomous endpoint management
These are the capabilities that cover the endpoint lifecycle, from keeping software current to restoring a device after a failure:
Autonomous patch management
Autonomous patching covers the operating system and third-party applications. The platform scans devices, ranks findings by risk using severity and exploit information, and deploys fixes in stages, widening each stage only while results stay healthy. NIST describes enterprise patch management as a cycle of identifying, prioritizing, acquiring, installing, and verifying patches, updates, and upgrades across an organization, in its guide NIST Special Publication 800-40 Revision 4. Autonomous patching automates that whole cycle, including the verification step. See What Is Patch Management? for the wider discipline.
Configuration enforcement and drift remediation
Every endpoint should match an approved baseline: encryption on, firewall enabled, required software present, risky settings off. Over time devices drift from that baseline because of user changes, failed updates, or new installations. AEM compares actual state with the baseline continuously and corrects deviations automatically, maintaining a consistent and trusted state across the fleet, which is how organizations stop endpoint configuration drift before it becomes a security gap.
Self-healing applications and security controls
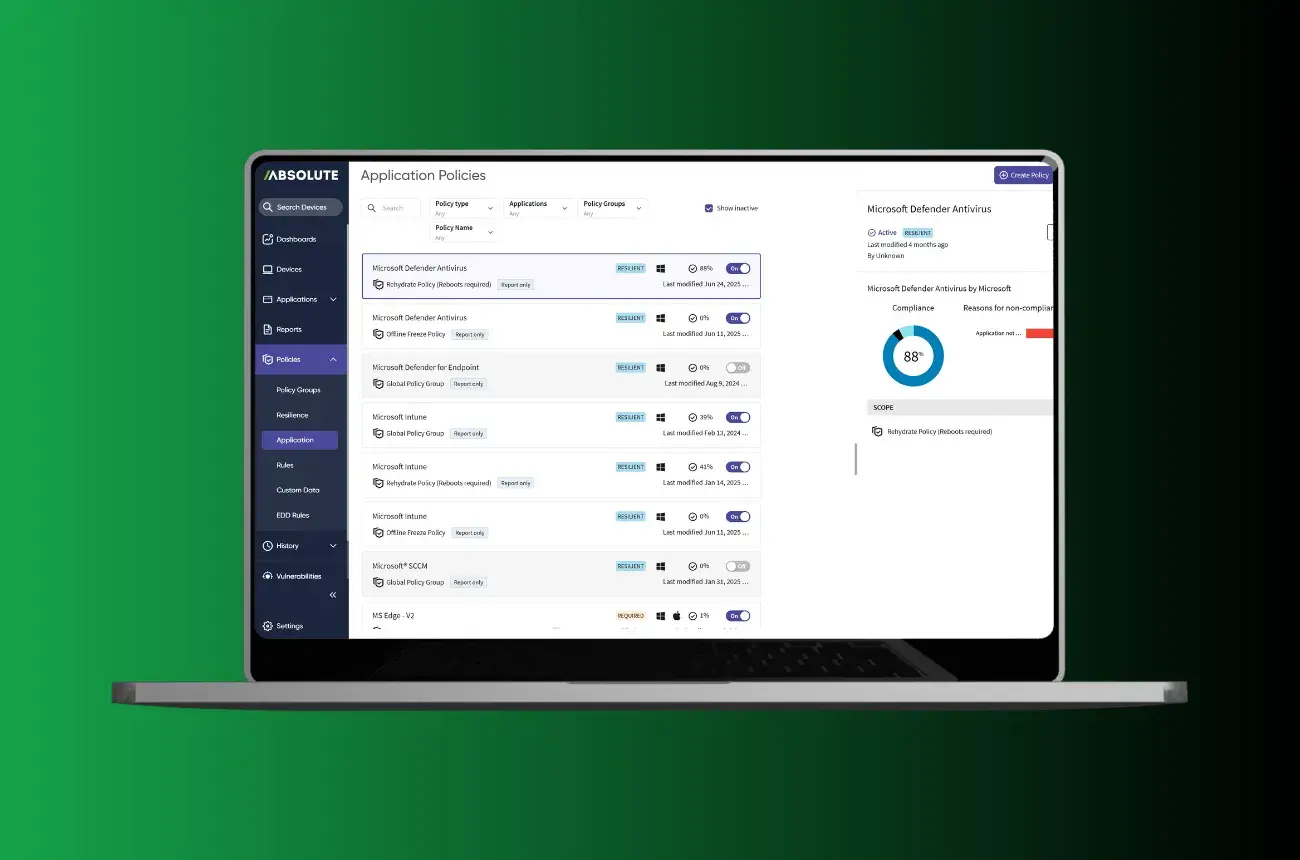
A self-healing endpoint monitors the health of designated applications and repairs or reinstalls them when they fail, are tampered with, or are removed, which keeps security applications healthy and running without a technician. This matters most for the controls that protect everything else: endpoint protection, encryption, VPN clients, and management agents
Automated device recovery
When a device is compromised, corrupted, or out of compliance, AEM can return it to a known-good state remotely, which helps teams accelerate incident response and endpoint recovery, with no shipping hardware and no technician visit. For distributed fleets that turns days of logistics into a background process. See the incident response and endpoint recovery use case.
Real-time device intelligence
Autonomy is only as good as the data behind it. AEM relies on continuous telemetry: hardware and software inventory, patch level, application health, encryption status, location, and usage signals. This feeds decisions about what to fix first, and it gives IT a trustworthy picture of the fleet. Accurate endpoint data also keeps downstream systems honest, as described in the use case on fixing CMDB accuracy.
Policy guardrails, audit trails, and rollback
Autonomy without control is a liability. Administrators define what the platform may do by policy, device group, and risk level. Every action is logged with what was done, to which device, and why, and changes can be reversed. That is what lets organizations extend autonomy step by step.
Benefits of autonomous endpoint management
The benefits below all follow from one change: the platform handles the routine work, and people handle policy and exceptions
Faster, more consistent remediation
Because the platform acts as soon as it detects a problem, the time between detection and verified fix drops. Every device is held to the same standard, and low-priority machines no longer wait at the back of a manual queue.
Less repetitive work
Routine tasks such as retrying failed patches, reinstalling agents, and correcting drift move to the platform, which cuts ticket volume and frees skilled staff for work that needs human judgment. See how teams streamline IT and security operations.
Stronger security posture
Proactive security controls, current software, and enforced configuration shrink the attack surface. The posture also stays stable because deviations are corrected continuously and not at the next maintenance cycle.
Continuous, audit-ready evidence
Every action logged with its outcome gives compliance teams a running record of device state and remediation. Instead of assembling evidence before each audit, organizations can prove compliance continuously as a by-product of the work.
Autonomous recovery and resilient operations
When a device fails or is compromised, remote recovery to a trusted state shortens downtime, which ties AEM directly to cyber resilience, the ability to keep operating through disruption and to recover quickly.
How is autonomous endpoint management used across industries
AEM tends to matter most for large or distributed fleets, especially where on-site IT access is limited. The table shows where that pattern appears most often and what the platform keeps working in each sector.
The common thread is devices outside the reach of a technician that still need to be patched, configured, protected, and recoverable.
Challenges and common misconceptions of AEM
Autonomous endpoint management is not a cure-all, and a few misunderstandings come up often.
- Autonomous does not mean unattended. People stay accountable for policy, thresholds, and exceptions, and every automated action is visible and reversible.
- Data quality and change management decide the outcome. Autonomous decisions rely on accurate inventory and telemetry. If device data is incomplete or policies are unclear, autonomy amplifies the confusion. Processes, roles, and approvals also need to adapt as work moves from manual to automated, and starting with low-risk actions and widening gradually is the usual remedy.
- Not every task should be autonomous. Some changes carry enough business risk, such as updates to systems that support critical operations, that a human approval step is the right design. Good platforms let organizations choose where autonomy applies.
How autonomous endpoint management relates to other endpoint terms
Several terms overlap with autonomous endpoint management and are often used interchangeably. These are the ones most often confused with it.
AEM and unified endpoint management (UEM)
As explained earlier in this piece, UEM describes breadth: managing many device types and operating systems from one console. AEM describes how the work gets done: with intelligence-driven automation and closed-loop remediation. The two are not in competition. A UEM platform can adopt AEM capabilities, which is a natural direction for the market to take.
AEM and endpoint security
Endpoint detection and response tools look for malicious behavior and respond to threats. AEM focuses on the operational state of the device: whether it is patched, correctly configured, running its required software, and recoverable. It keeps detection tools alive and the device in good hygiene, which reduces what detection has to catch. For the protective side, read What Is Endpoint Security?
AEM and digital employee experience (DEX)
Digital employee experience tools measure how devices and applications perform from the user's side: slow start-up times, crashes, network problems. AEM can use those measurements as signals, for example to judge whether a patch has degraded performance, and it can act on what they reveal.
AEM and autonomous IT operations
Autonomous IT operations apply the same detect, decide, act, and verify model across the whole IT estate, including servers, cloud services, and networks. AEM is the endpoint-focused part of that picture.
Conclusion
Autonomous endpoint management changes who does the routine work of keeping devices healthy. The platform detects problems, decides what to do within the rules people set, acts, and confirms the device is back in the right state, often before anyone opens a ticket. It keeps working even when a device has been reimaged or an agent has been removed. People stay in charge of policy and exceptions, every action is logged and reversible, and autonomy grows in stages as results earn trust. The outcome is endpoints that stay patched, protected, and recoverable without adding more manual effort.
FAQs
Unified endpoint management (UEM) provides breadth and a single control point across device types. Autonomous endpoint management adds decision-making and verification on top of it. Organizations combine them in three ways: AEM built into the UEM platform, a separate autonomous platform alongside it, or an autonomous layer beneath it that keeps devices reachable. None requires replacing the UEM.
No. Automation runs fixed steps when a trigger fires, such as a patch job at a set time, and reports that the job completed. Autonomous endpoint management decides whether to act and which devices come first, rolls changes out in stages, and confirms on the device that the intended state was reached, retrying or rolling back if it was not.
No. Endpoint detection and response tools find and respond to malicious activity. Autonomous endpoint management keeps devices patched, correctly configured, running their required software, and recoverable. It also repairs security tools that fail, so it supports detection tools and does not replace them.
No. People write the policy, set the limits on what the platform may change, and review exceptions and outcomes. Every automated action should be logged and reversible. Most organizations extend autonomy in stages, starting with low-risk tasks, as results build trust
Six capabilities recur: operating system and third-party patching, configuration enforcement and drift remediation, repair or reinstallation of failed security tools and applications, remote recovery to a trusted state, continuous device telemetry, and policy guardrails with audit trails and rollback.
Ask whether the platform decides and verifies or only executes, and whether it can reach every device in every condition. Check that you can set, see, and reverse its boundaries, and that it works with your identity, security, service management, and UEM tools. Finally, confirm it supports the operating systems in your fleet.